AI engineer · Yerevan, Armenia · open to relocation and remote
AI engineering, from research to release.
I work on every step in between, mostly in language AI: retrieval, evaluation, agents, the API around them and the deploy. Each project below says what was measured; hover or tap a numbered marker to see its source.
01
Research · BSDS capstone · January to May 2026
Small students that match their LLM teacher on Armenian punctuation
The first neural approach to punctuating Armenian participle clauses.1 Gemini 2.5 Flash, prompted with a linguist's rules, labelled 112K sentences. Small students learned from those labels, and the best of them runs on a laptop CPU.
- 0.675macro-F1 for the BiLSTM + mBERT ensemble on Shtemaran 2922
- 0.700macro-F1 for the Gemini 2.5 Flash teacher on the same set2
- 112Ksentences labelled by the teacher
The problem
Participle phrases ending in -ելով, -ալով or -ած take a comma or the Armenian buth (՝) depending on where they sit in the sentence, and educated native writers routinely get them wrong. We framed the fix as token classification with four labels: O, COMMA_AFTER, BUTH_AFTER and REMOVE_COMMA.1
Նա տեսնելով Արմենին տխրեց
Նա, տեսնելով Արմենին, տխրեց։
The pipeline
- OSCAR 23.0122M Armenian web sentences
- Filterparticiple endings and Stanza POS, 120K sampled
- TeacherGemini 2.5 Flash with a linguist-curated prompt, 112K labelled
- StudentsBiLSTM, mBERT, HyeBERT, tuned with Optuna
- EnsembleBiLSTM + mBERT soft vote, α = 0.45
The BiLSTM has one layer of 128 hidden units over frozen 300-d Armenian GloVe vectors: 48.5M parameters, 48.1M of them the frozen embedding table, tuned over 25 Optuna trials. mBERT keeps its lower 6 of 12 layers frozen, tuned over 21 trials.15
Results
| Model | Shtemaran 292 | Shtemaran 292, as bars | Gold 2K |
|---|---|---|---|
| BiLSTM | 0.366 | 0.412 | |
| HyeBERT | 0.326 | n/a | |
| mBERT | 0.519 | 0.466 | |
| Ensemble, α = 0.45 | 0.675 | 0.465 | |
| Gemini 2.5 Flash, teacher | 0.700 | n/a |
- Within 0.025 of the teacher. 0.675 against 0.700 macro-F1 on Shtemaran, a difference McNemar's test cannot separate from chance (p = 0.111).2
- Better than the teacher at commas. COMMA_AFTER F1 was 0.527 for mBERT and 0.494 for the ensemble, against 0.449 for Gemini: the students filtered out part of the teacher's label noise.1
- Depth beat language-specific pretraining. Multilingual 12-layer mBERT (0.519) outperformed the 6-layer Armenian HyeBERT (0.326).2
- Cheap to run. The BiLSTM labels over 1,000 sentences per second on a laptop CPU and mBERT about 20, where the teacher costs about $0.003 per sentence through an API.1
On the noisier Gold 2K set the ensemble only ties mBERT (0.465 against 0.466).
02
Noetrix · open-source RAG engine · June 2026 to now
A RAG engine where every default had to win a paired test
Noetrix answers from your own documents and nowhere else: inline [n] citations, a confidence line, and a plain “nothing relevant” when the corpus is silent. Retrieval runs locally on CPU; only the final answer calls a model, through any OpenAI- or Anthropic-compatible endpoint.6 My own instance covers a 100 GB Obsidian vault: 170K+ chunks from 4,500+ documents of textbooks, coursework, notes and code.
- 0.758nDCG@10 for the shipped pipeline7
- 0.856recall@10 for the shipped pipeline7
- 396verified questions as of 31 October 2026, with a dev split and a sealed test split7
The shipped query path
- Dense laneChromaDB, bge-small-en-v1.5 on CPU
- Sparse laneBM25 through bm25s
- FusionReciprocal Rank Fusion, k = 60, weighted lanes
- RerankMiniLM-L6 cross-encoder, in process
- Answer[n] citations, a confidence line, an optional citation audit
A code lane opens only when a question asks for code. Text an LLM wrote, such as generated maps and summaries, is never evidence.6
What each stage bought
Each rung of the ladder adds one stage on the same index and the same 179 answerable dev questions. Δ is the paired change against the rung above, with a 95% bootstrap interval. A step counts as real only when its interval excludes zero, a rule fixed before the runs.7
| Step | nDCG@10 | Paired Δ, 95% interval | Interval plot | Verdict |
|---|---|---|---|---|
| BM25 only | 0.675 | base | ||
| Dense only | 0.674 | −0.001 [−0.063, +0.058] | noise | |
| + fusion (RRF) | 0.710 | +0.037 [+0.003, +0.071] | real | |
| + scope routing | 0.670 | −0.040 [−0.069, −0.015] | real, worse | |
| + code lane | 0.656 | −0.014 [−0.038, +0.007] | noise | |
| + cross-encoder rerank | 0.758 | +0.103 [+0.056, +0.151] | real |
Shipped pipeline: nDCG@10 0.758, recall@10 0.856. Warm retrieval on CPU takes 3.36 s at the median, 88% of it in the reranker.7
Tried, measured, switched off
Each idea below costs something on every query. On the reranked pipeline each measured as noise or worse, so each ships off. That includes HyDE, which the live config ran until 0.29.0.7
| Idea | Paired Δ nDCG@10 | 95% interval |
|---|---|---|
| HyDE, drafts by gpt-oss-120b | −0.020 | [−0.044, +0.000] |
| HyDE, drafts by Claude Sonnet | −0.018 | [−0.047, +0.007] |
| Scope routing, after the rerank | ±0.000 | [±0.000, ±0.000] |
| At most 2 chunks per file | −0.001 | [−0.012, +0.009] |
| Query decomposition | +0.001 | [−0.009, +0.011] |
Bigger models, measured
- A larger reranker, bge-reranker-v2-m3, beats the shipped MiniLM by +0.046 [+0.017, +0.076] nDCG@10, but costs about 22 times as much on CPU. It waits for a GPU and a controlled latency test.7
- EmbeddingGemma 2 added +0.004 after reranking at either size, not enough to pay for a full re-embed, so bge-small stays.7
- Laya, a 421M-parameter ModernBERT-large student distilled from bge-reranker-v2-m3 on one Kaggle T4, scored nDCG@10 0.722 against MiniLM's 0.667 on 45 held-out passages. The gain, +0.055 [−0.017, +0.127], is not significant, so Laya stays behind a flag until a full run.9
Findings that changed the code
- Summaries crowded out their sources. Indexing 1,148 LLM-written map rows cost −0.227 nDCG@10 [−0.291, −0.165] on the 35 questions about the topics they cover, and 41% of the final lists were generated. Since 0.30.0, generated text never grounds an answer and every source carries its provenance.8
- The fix failed its own latency gate first. A Chroma
$nefilter took the dense lane from about 12 ms to 630 ms, +28.6% on total median latency against a +5% limit. Over-fetching and filtering in Python kept exactly the same rows at +1.2%.8 - A minute-long graph walk now takes two seconds. Moving a page-range test out of the Chroma where-clause cut walks from 46–64 s to 1.6–2.0 s, with byte-identical output.8
Where it still fails
Questions that need two or more sources score 0.585 nDCG@10, and questions I wrote myself score 0.398 against 0.806 for LLM-drafted ones. Of 37 missed gold sources, 19 never reach even the top 50 fused candidates, so the next gain is on the query side: searching again with what the first pass found. Answers graded by an LLM judge, advisory until a human-agreement check, reach nugget recall 0.831 and citation precision 0.999.7
03
Argus v4 · multi-agent research bot · June 2026 to now
A research agent that cuts the claims it cannot support
One Telegram command returns a cited report as Markdown and PDF, plus an evidence.json. Links come only from live search or from the user, quotes are checked word for word, and a claim that fails its judge moves out of the body into an appendix.11
- PlanThe user sends a research command; Argus replies with a plan that lists the sources live search found.
- ApproveThe user approves it.
- ReadingReading sources, judging claims.
- ReportArgus delivers a cited report as Markdown, PDF and an evidence file.
One run through the graph
- intake
- brief
- scout
- plan gate
- research
- outline
- compose
- analyst
- panel
- report_builder
- report gate
- deliver
Twelve nodes, counting extend_prep and revise_prep, which carry Extend and Revise back into research and compose. The panel can also send a run back for a bounded gap wave or a targeted rewrite, and /ask takes a three-node quick path.12
- Two human gates. Both are LangGraph interrupts. The plan gate shows the sources that live search actually found; the brief holds no URLs, so the model has no links to invent. The report gate offers Send, Extend, Revise or Cancel.11
- Evidence first. Every fetched document is digested into claims with verbatim-checked quotes. Section writers compose only from those notes, and the analyst's worked numbers check each input against the finding it cites.11
- A panel that can cut. A batched grounding judge checks every finding against its quotes, next to a coverage review and a deterministic precision scan. Rejected claims leave the body, and a report the judge could not check says “Not fact-checked” at the top.11
- Engines you can audit.
argus_engines.jsonbinds each pipeline role to a provider and model, with declared fallbacks: a free proxy by default, or OpenAI-compatible, Anthropic, Gemini, Groq, OpenRouter, Ollama and LM Studio. Each call logs the requested and the served model, and a fallback is printed in the report, never silent.11 - Around the core. A Telegram Mini App console over a cloudflared tunnel with live progress and tap-to-verify citations; a media library for YouTube, X, Reddit and Instagram with faster-whisper transcription; a five-strategy URL resolution cascade adapted from NVIDIA's AI-Q blueprint, with domain-trust scoring; runs checkpointed in SQLite, so they survive restarts.1112
04
Team project · AUA NLP course · May 2026
A custom Armenian tokenizer cut Qwen2.5's token count by 78%
General-purpose tokenizers break Armenian words into many pieces, which wastes context and compute. We measured how badly, trained our own tokenizer, grafted it into Qwen2.5-0.5B and recovered the model with LoRA.13
- 78%cut in Qwen2.5's token count13
- 7.83 → 1.69tokens per word for Qwen2.5-0.5B, before and after grafting 30,766 Armenian tokens13
- 92.6%of our BPE-32k vocabulary is Armenian, against 1.4% for XLM-R13
Tokens per Armenian word, lower is better
Measured on 516,860 words in 25,621 lines of Armenian. Our BPE-32k also led on bytes per token (8.72), single-token word retention (0.683) and severe fragmentation (2.5%), and 92.6% of its vocabulary is Armenian, against 1.4% for XLM-R.13
Grafting and recovery
| How the new rows were initialized | Before | After LoRA |
|---|---|---|
| Heuristic, FOCUS-style | 24,484 | 8.33 |
| Nearest token | 96,968 | 8.96 |
| Mean embedding | 216,406 | 10.09 |
An English-preservation check showed no collapse: the heuristic model's English perplexity was 19.9.13
05
Other work
Coursework that shipped as working software
-
Agentic teaching assistant
Upload a lecture PDF and six agents build a timed study session: slide parser, concept map, web research, planner, reviewer and email. Email stays blocked until the reviewer passes the plan. It runs on a local Mistral-Nemo 12B through KoboldCpp and writes in English or Armenian.
Repository -
Pulse, a free-to-paid conversion platform
My part was the backend of a five-service Docker Compose stack: FastAPI, PostgreSQL 16, Streamlit, Jupyter and an ETL seeder, with 20+ REST endpoints over SQLAlchemy and Pydantic v2. Logistic regression scores conversion by behavioural segment, and Thompson sampling runs the A/B tests.16
Repository -
Soil moisture after wildfire
Cut a 116-column geospatial dataset to 48 non-collinear features, then compared models on identical splits. Gradient boosting led (R² 0.383) over random forest (0.357), while an MLP collapsed to R² −22.4 on 900 samples, and the comparison was repeated at 1,800.
Repository -
Shanghai transportation analysis
Bike-share, taxi and bus GPS data from Shanghai, explored with statistical models, clustering and geospatial views, and served as an R Shiny dashboard built on leaflet, sf and plotly.
Repository
06
Credentials · 32 documents
Every credential opens its certificate
The degree, the showcase award and the certifications I use in applications come first. The register below lists every certificate with its date, length and number.
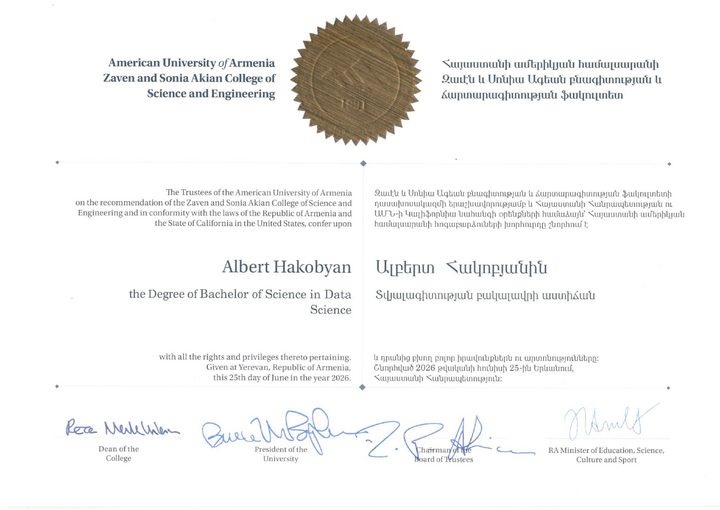
Degree
B.S. in Data Science
American University of Armenia ·
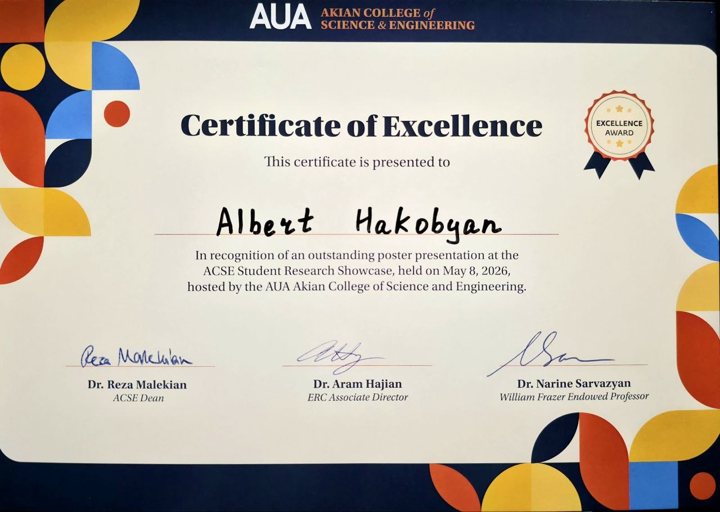
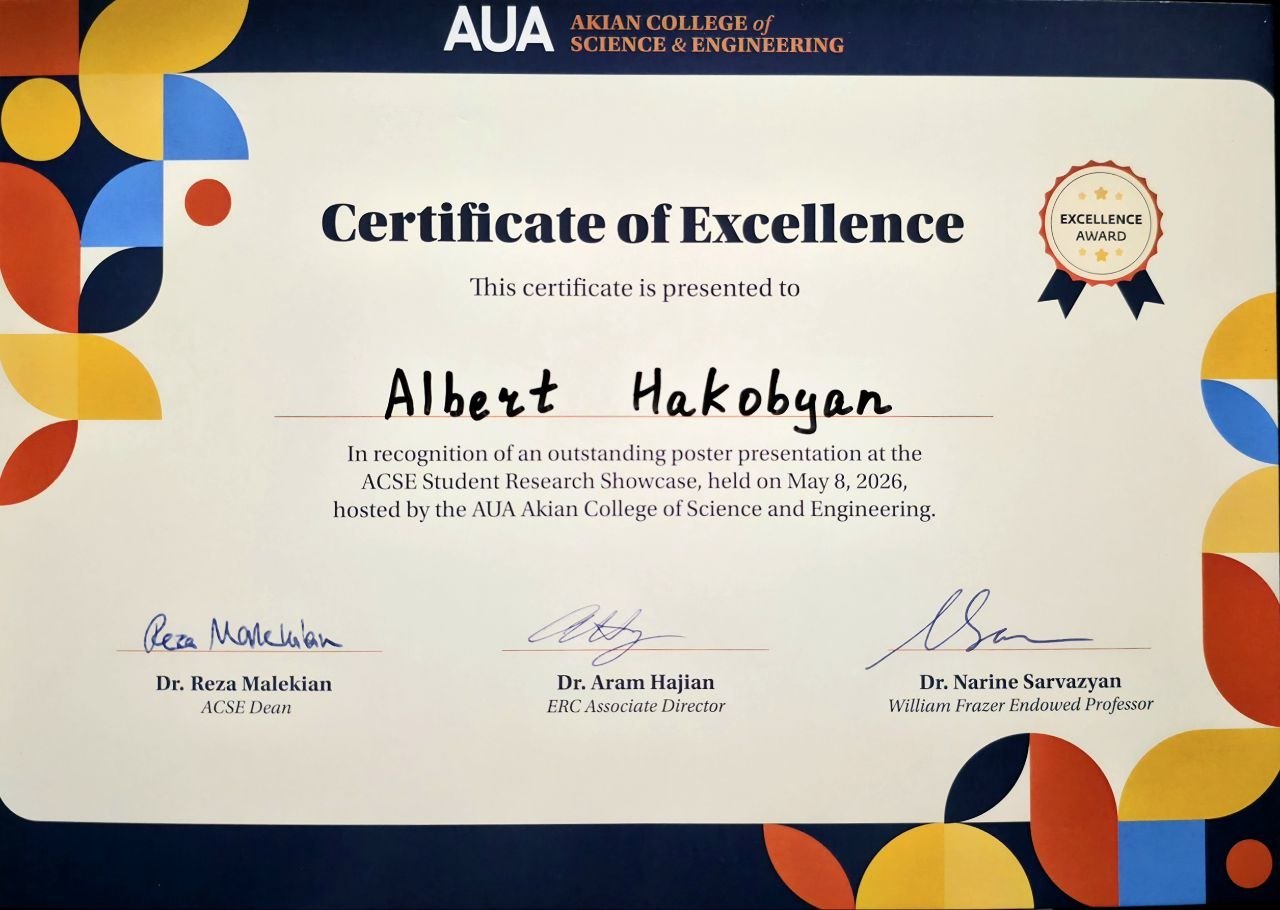
Award
Certificate of Excellence, ACSE Student Research Showcase
AUA Akian College of Science and Engineering ·
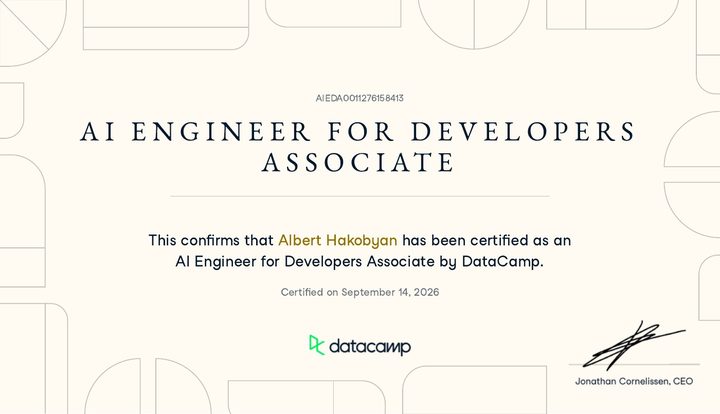
Certification
AI Engineer for Developers Associate
DataCamp ·
Career track · 29 h
Associate AI Engineer for Developers
DataCamp ·
Career track · 10 h
AWS Cloud Practitioner (CLF-C02)
DataCamp ·
Specialization · 4 courses
Natural Language Processing
DeepLearning.AI on Coursera ·
Course · 4 h
Reinforcement Learning with Gymnasium in Python
DataCamp ·
The full register
07
Toolkit and education
What I work with, and where it shows
- LLMs and agents
- LangGraph (Argus) · LangChain · hybrid dense and sparse retrieval, RRF and cross-encoder reranking (Noetrix) · Model Context Protocol servers (Noetrix) · retrieval evaluation with paired bootstrap intervals · local serving with Ollama, vLLM and KoboldCpp
- ML and NLP
- PyTorch · Hugging Face Transformers · knowledge distillation and token classification (thesis) · SentencePiece, LoRA and PEFT (tokenizer project) · Optuna · scikit-learn
- Backend and data
- Python · FastAPI · Pydantic · SQLAlchemy · PostgreSQL · SQLite · async Python · Docker and Compose · GitHub Actions · pytest · SQL · R
- Statistics
- Inference and non-parametric tests · Bayesian statistics · regression · A/B testing and Thompson sampling · survival analysis · time series
- Languages
- Armenian · Russian · English
B.S. in Data Science, American University of Armenia
Natural language processing
AUA NLP course, the Coursera NLP Specialization and the capstone: word embeddings, RNNs and LSTMs, transformers and attention, pretraining and fine-tuning, RLHF and GRPO, retrieval-augmented generation and agents.
Machine learning and AI CS 251 · CS 246 · DS 232
Regression and regularization, SVMs and kernels, trees and ensembles, neural networks and CNNs, clustering and PCA, reinforcement learning from MDPs to actor-critic, GANs, VAEs and diffusion models.
Statistics and inference CS 108 · DS 110
Estimation and its properties, confidence intervals, hypothesis tests, linear, logistic and Poisson regression, non-parametric tests, Bayesian inference.
Time series CS 362
Stationarity, exponential smoothing and Holt-Winters, ARIMA to SARIMAX, GARCH, VAR and the Kalman filter.
Business intelligence and marketing analytics DS 206 · BSDS 227 · DS 223
Power BI and DAX, Tableau, dimensional modeling and ETL, the Bass model, conjoint analysis, A/B testing and bandits, customer lifetime value and survival models, RFM and cohort analysis.
Programming, databases and visualization DS 120 · DS 205 · DS 116
Python and R, SQL and the relational model, normalization, indexing and transactions, MongoDB, ggplot2, Plotly and R Shiny.
Mathematics ENGS 101 · CS 102 · CS 104 · CS 112
Single and multivariable calculus, vector calculus, linear algebra, numerical methods and optimization.
Contact
Hiring for retrieval, agents or NLP? Write to me.
I am in Yerevan (UTC+4) and open to relocation and remote work. Email is the fastest way to reach me.
Albert.Hakobyan@proton.meSources
Where each number comes from
Repository counts were taken on 1 November 2026. Noetrix bench numbers come from its run records, which stay private because they quote the vault; the run identifiers are listed so each figure can be traced.
- A. Hakobyan, A. Hovhannisyan, S. Kumar. Sequence Labeling for Low-Resource Syntax: Automatic Punctuation of Armenian Participle Clauses. BSDS capstone paper, American University of Armenia, 2026. PDF on cse.aua.am
- Thesis repository, “Key Results” table. github.com/AlbertHakobyan070/Armenian-participle-phrase-punctuation
- AUA Newsroom, “ACSE Hosts Second Annual Student Research Showcase,” 21 May 2026: more than 120 projects, 16 recognized with Trophies of Excellence, 12 judging teams of faculty and industry professionals. newsroom.aua.am
- Certificate of Excellence, ACSE Student Research Showcase, 8 May 2026. Scan
- Model cards and weights on Hugging Face: mBERT, BiLSTM, HyeBERT. The BiLSTM checkpoint holds 48.5M fp32 values, 48.1M of them the embedding table.
- Noetrix README and changelog, release 0.32.1, 1 November 2026. github.com/AlbertHakobyan070/Advanced-Obsidian-RAG, documentation
- Noetrix Eval Ledger, dev split, 179 answerable questions: ladder run 20261011-031642; reranker run 20261013-214201; HyDE runs 20261011-211158 and 20261014-011301; cap run 20261013-235021; decomposition run 20261014-032420; shipped-pipeline runs of 13 and 14 October 2026. Question-set counts as of 31 October 2026.
- Noetrix Eval Ledger §14 and commits: generated-content runs 20261027-094003 against 20261027-112019; latency-gate runs 20261028-183309, -184930 and -185516 with commits aceb41c and 6ca60cb; graph-walk fix in commit 136f5b4, 30 October 2026.
- Laya reranker distillation, step-one mini-run on a Kaggle T4, 14 October 2026.
- Counts from each repository's default branch on 1 November 2026: lines in non-test Python files, test files named
test_*.py, and functions namedtest_*. - Argus README and the “How it works” documentation. github.com/AlbertHakobyan070/argus-research-bot, how it works
- Argus source: graph.py (the graph), citations.py (the URL cascade from NVIDIA AI-Q), credibility.py (domain trust), ci.yml.
- Tokenizer-surgery results: goal5_final_results.json, with the goal 1 and goal 2 result files in the same repository.
- Diploma, B.S. in Data Science, American University of Armenia, 25 June 2026. PDF
- DataCamp, AI Engineer for Developers Associate, certification AIEDA0011276158413, 14 September 2026. PDF
- Pulse repository and its six contributors. github.com/AlbertHakobyan070/marketing-analytics-Free-to-Paid-Conversion-Platform